
Developers
Contribute to ai-memory
140 people have landed code so far. This page gets you from an idea to the right issue, the right crate and a pull request that passes review the first time.
An active project, in numbers
Counts come from the GitHub API when this site is built.
Top contributors
akitaonrails
djalmajr
viniciusdsandrade
everton-dgn
samirhvbr
lucasliet
felipe-NR
wblech
kevin9327
rthiago
maxeinstein-dev
matheus-rodrigues00
luisfnicolau
petersonsalme
rubenlr
talyssonoc
rafaelkenedy
evanmaranzano
JohnC0de
pablowinck
gabrielscharb
lhzapata
abhisheksharma2411
aguirreSL
caminhar-deus
gb
rntjr
mrpaiva
rodrigopalhares
yubr-zzh
lihuiyang1024
GrYllO
giovannirco
pvpmartins
atirna
Murillofilho86
mobnix
vitorvilas
zanlucathiago
Cardosaum
alvadorn
victorcesc
pedrofjr
enrell
davividal
Barba2k2
alanhoff
ArtroxGabriel
seathatflowsinourveins
milesibastos
klebervirgilio
iagogfe
dk96-creator
juniorgaudencio00-code
BobDylans
bcosta19
Gaalbu
cateim
Pick your way in
Each of these goes to the exact page on GitHub.
Report a bug
The template asks for your version, OS, agent, transport and the relevant server log lines.
Open a bug reportPropose a feature
Proposals are issues; the repository has no discussions board. The template asks what problem it solves and whether it would break existing installs.
Open a feature requestFind a first issue
The good first issue label marks work that suits a newcomer. Help wanted marks the rest.
Browse good first issuesAdd or fix a harness
Managed harness support has a written protocol: prove the native session contract, read stores read-only, deliver context before acknowledging it, and ship the required tests.
Read the harness protocolImprove the docs
Guides live in docs/ as markdown. A doc fix is a normal pull request and skips the changelog when nothing user-facing changes.
Browse docs/Build around it
Importers, richer UIs and chat front ends belong in companion projects that use the public HTTP and MCP surfaces.
Read the companion rules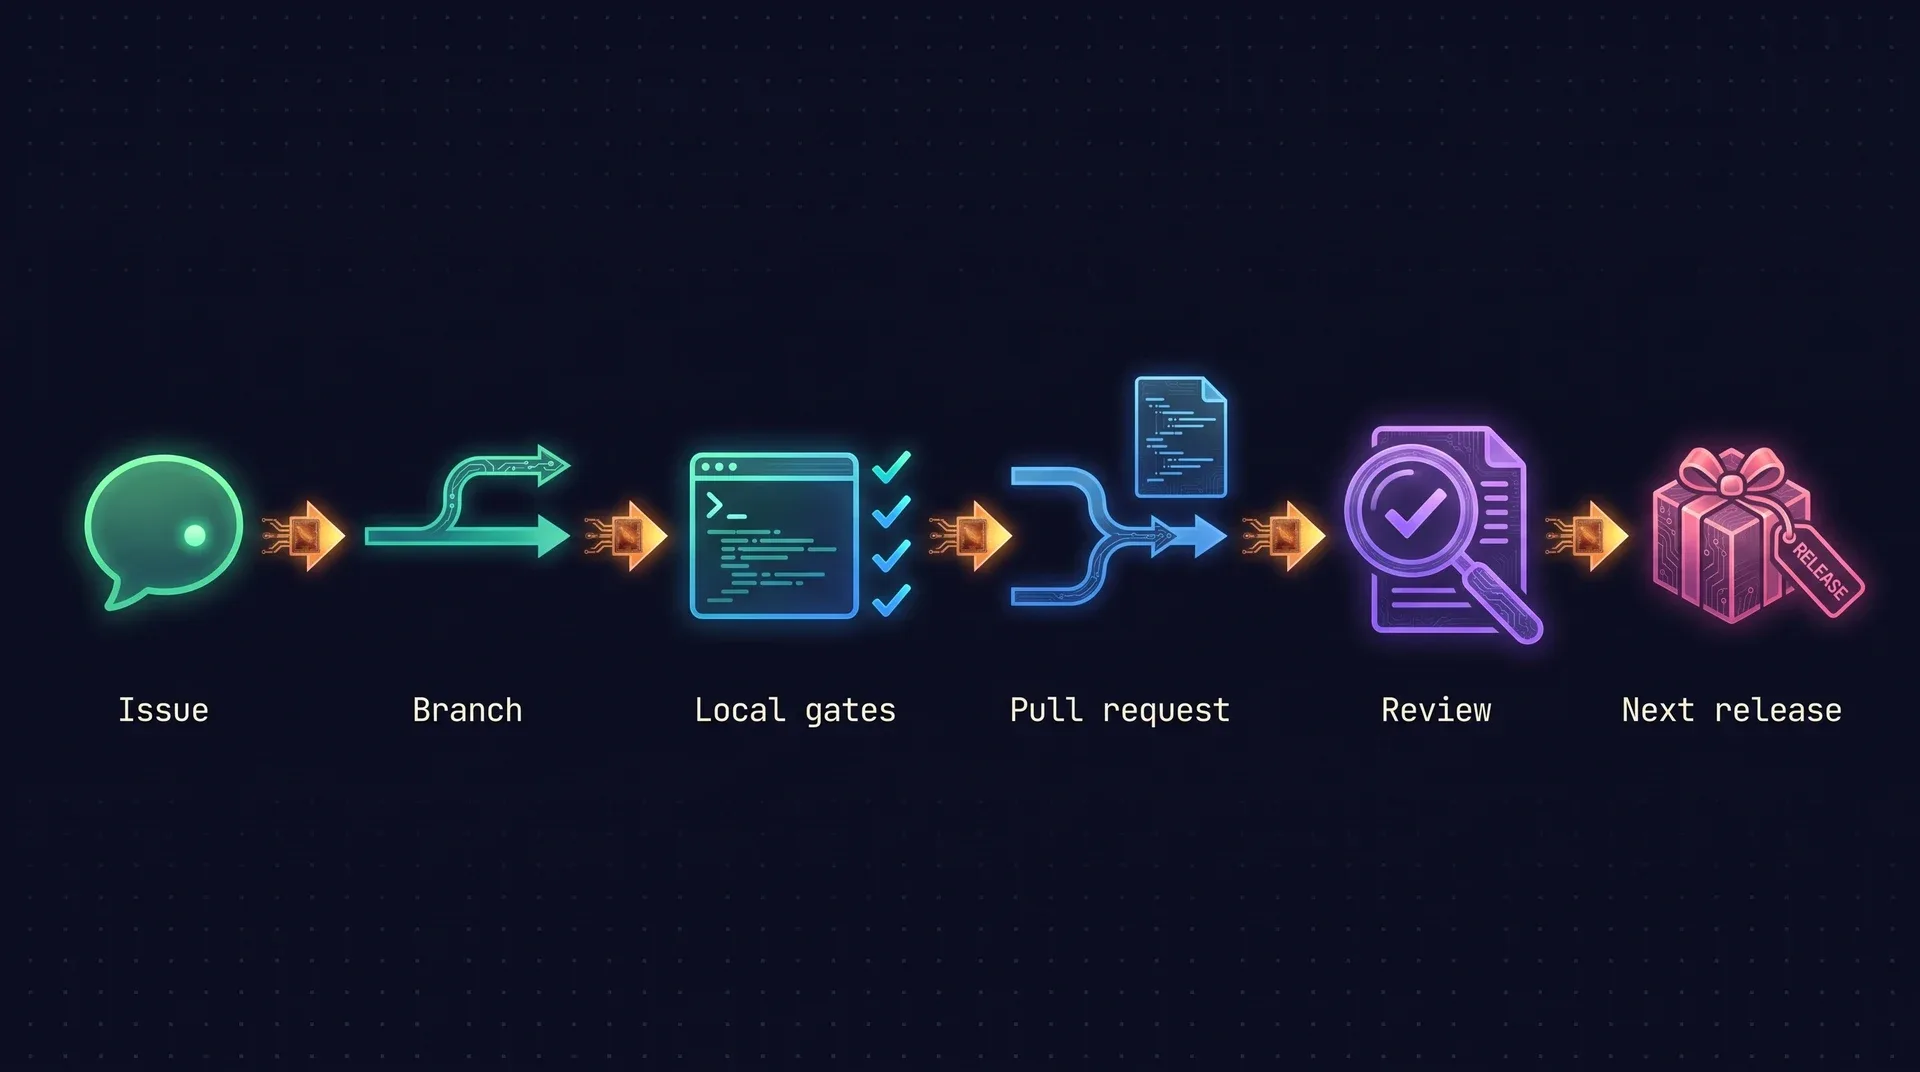
Get it building
The build is self-contained. None of these commands needs an environment variable.
Clone and build
Rust 1.95 is required and pinned in
rust-toolchain.toml, with rustfmt and clippy, so rustup installs the right toolchain on first build. SQLite is bundled and libgit2 is vendored. You need a standard C toolchain and nothing else.dev setup git clone https://github.com/akitaonrails/ai-memory cd ai-memory cargo build --workspace cargo test --workspace --all-targetsUse the everyday loop
cargo tneeds nextest:cargo install cargo-nextest --locked. It skips modules namedsloworstress, which the pre-push hook and CI still run.while you work cargo t # all but the slow tier, ~20s warm cargo t -p ai-memory-store # one crate: builds only its test binaries cargo t -E 'test(/purge/)' # one topic (builds everything, runs a subset)Install the pre-push hook
Once per clone. It only touches its own block in
.git/hooks/pre-push. On a work-in-progress branch,git push --no-verifyskips it.once per clone scripts/install-git-hooks.shPass the gates before you push
CI enforces all five. Without nextest,
cargo test --workspace --all-targetsis the equivalent ofcargo tf. If the last one is missing:cargo install cargo-deny cargo-audit.required gates cargo fmt --all -- --check git diff --check cargo clippy --workspace --all-targets -- -D warnings cargo tf # every test (alias: cargo nextest run -P full) cargo deny check # dependency policyCheck who your commits say you are
Use an email verified on your GitHub account or its noreply address. History on main is never rewritten to fix attribution.
commit attribution git log --format='%h %an <%ae>' "$(git merge-base HEAD origin/main)"..HEAD
Ground rules and the acceptance bar
AGENTS.md is the canonical rules file for people and for coding agents. CONTRIBUTING.md condenses it to this.
How work is expected to land
The changelog is a merge gate
Every user-facing change adds an entry under [Unreleased] in the same pull request. Reviewers treat a missing entry as blocking. Refactors and test-only changes are exempt.
Tests before “done”
Work counts as done once it has tests, above all parsers, ID derivation and the retention math.
No dead code, no half-built features
Stubs are documented in the module comment with the milestone that will finish them.
Stay inside the change
Do not refactor code the current milestone does not need.
Comments explain why
A comment that restates the line above it gets removed.
Invariants a pull request cannot break
- All SQLite writes go through the single writer actor,
WriterHandle. - Config is read once at startup. No
std::env::varoutsideConfig::load. - File writes are atomic: tmp, rename, fsync. Never in place.
- Every wiki page is namespaced by
(workspace_id, project_id). - The CLI is a thin HTTP client. It never opens the SQLite file or the wiki directory.
The full list, with the bug each one prevents, is in AGENTS.md
How the bar stays high
AI writes most of the code. A person reads all of it, and nothing merges on trust. Every rule below exists because something went wrong once.
- 73written rules in AGENTS.md
- 16invariants no pull request can break
- 92documents: research, post-mortems, decisions
- 5,208tests, unit and integration
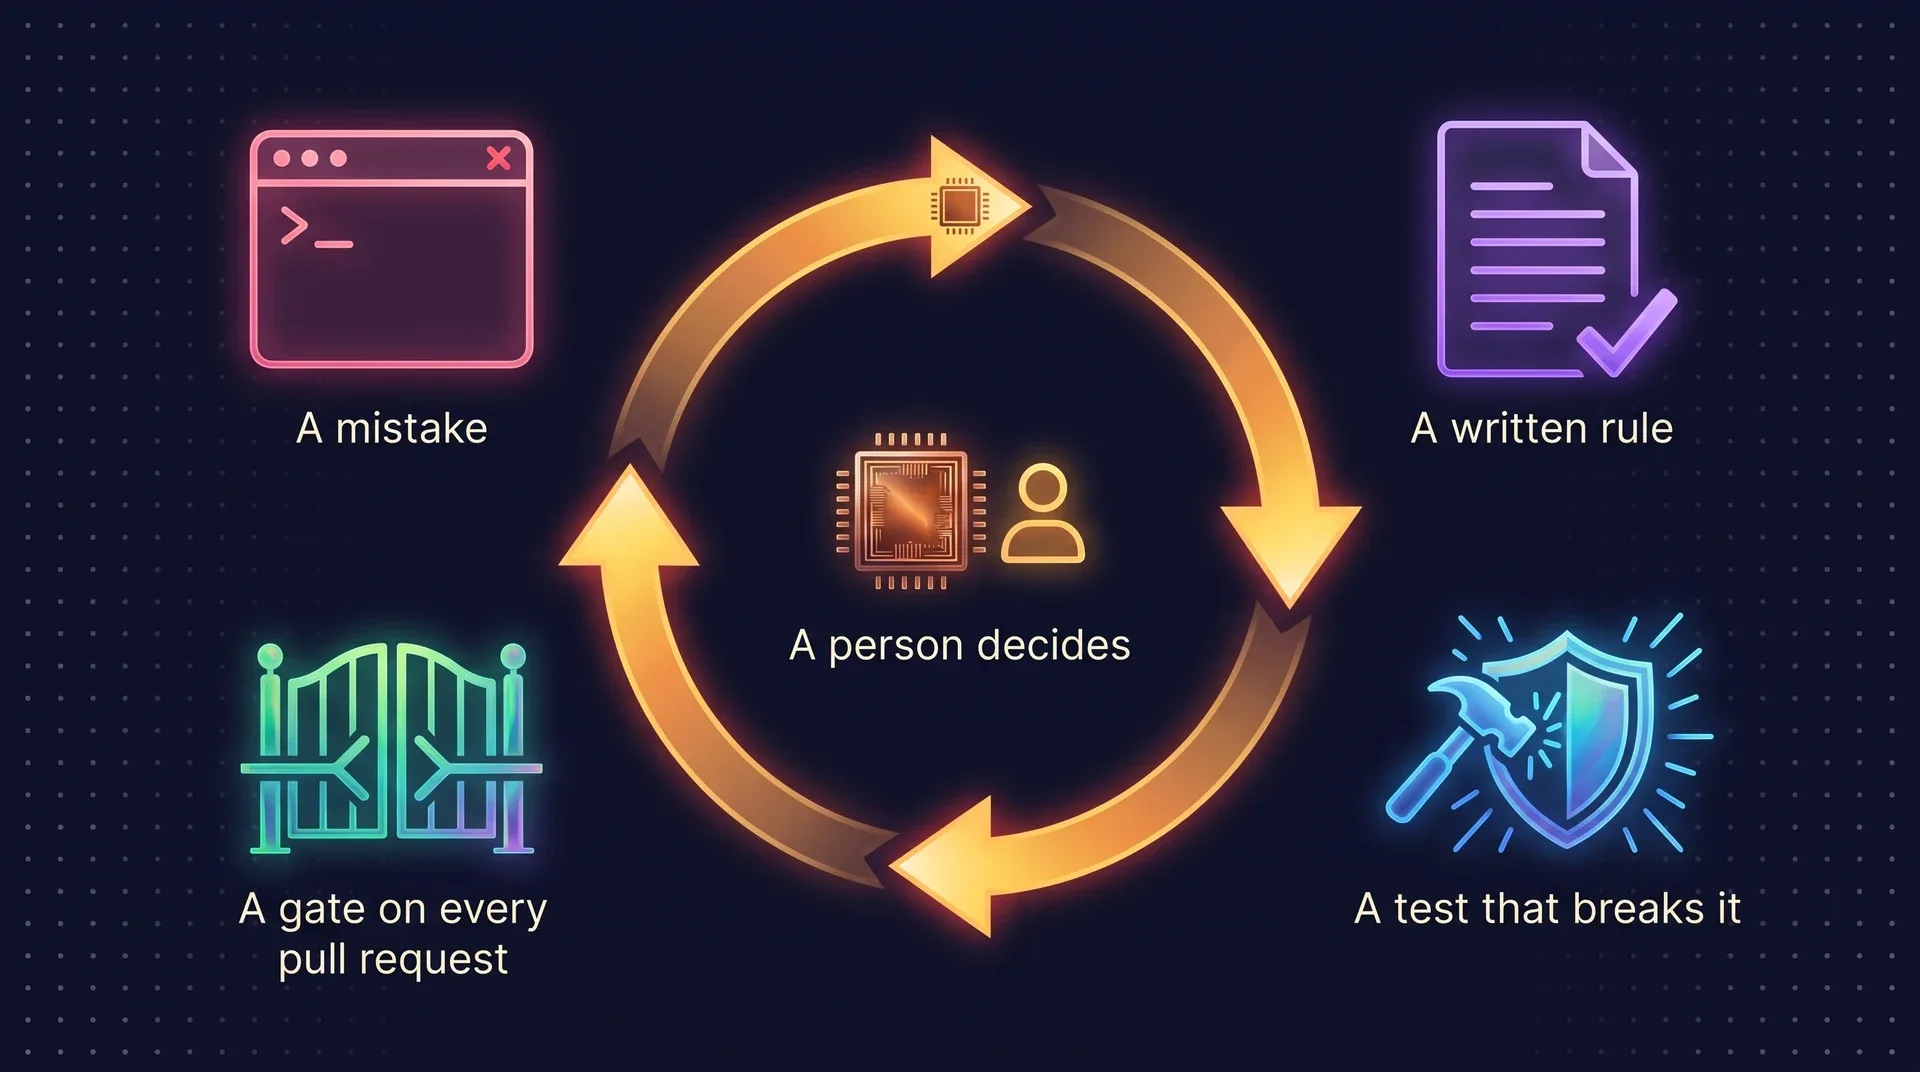
Rules come from errors
Each invariant names the bug that caused it and the code that prevents it. A rule nobody can trace to a failure gets removed.
Every pull request is audited
The claims in a pull request are checked against the code, the gates run again, and only what was verified merges. The audit checklists are public.
A person decides
The AI does most of the typing. The maintainer reads, corrects, and turns what went wrong into the next rule.
Two models, one audit checklist
A small experiment on ai-jail, the sandbox a --yolo run can be handed to. The same security-audit checklist, run by two models on the same commit, then compared.
The target
ai-jail runs a coding agent inside an OS sandbox: bubblewrap with Landlock and seccomp on Linux, sandbox-exec on macOS. It is a layer, not a substitute for a disposable machine when the code is hostile.
aijail.ioThe first run
Genesys Pi, driven through OpenCode, first did ordinary implementation work on ai-jail and landed it. Then it ran the security-audit skill from the public skills repository against v2.3.0.
The post about the skillsThe second run
Claude Fable 5.1 ran the same skill on the same commit without reading the first report. Once its list was fixed, it re-derived every shared lead from source and wrote the comparison.
- Found by both11
- Only Genesys Pi11
- Only Claude Fable 5.13
Same two Highs
Forged worktree metadata gave read and write on a host directory, and duplicate environment entries slipped past the phantom secret. Each model reproduced both without the other.
Genesys Pi went wider
Eleven findings only it reached, among them the whole macOS surface and the proxy’s resource limits, with sharper severity calls. Fable had rejected one real bug and left two others unresolved until the cross-check.
Fable found the sharpest miss
Two test-only escape hatches in the release binary, read from the environment, sat on the exact path the phantom credentials protect. It also ran the exploits where the other report reasoned about them.
A map of the codebase
Ten crates ship in the binary. Each has one responsibility and a typed API, and there are no circular dependencies.
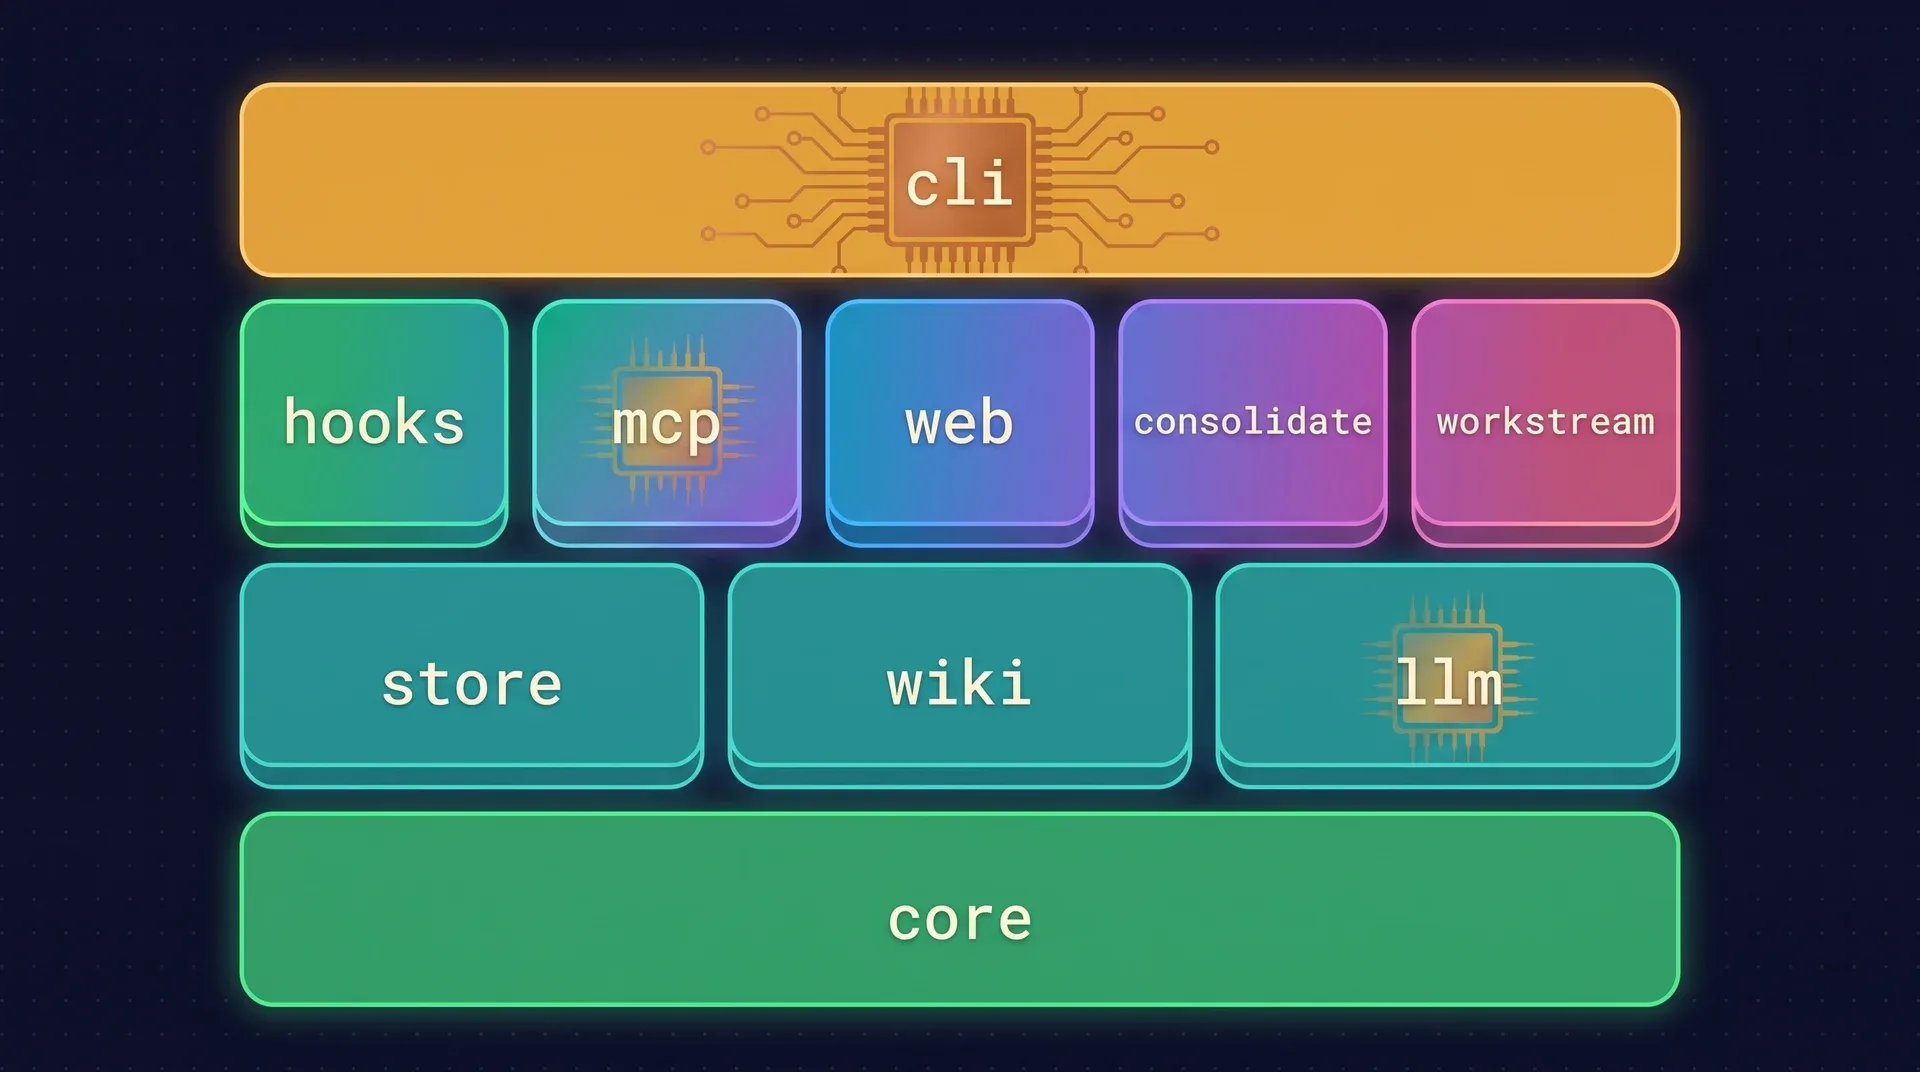
| Crate | What lives there |
|---|---|
ai-memory-core | Domain types, errors and ids. No IO. |
ai-memory-store | SQLite, the writer actor, the reader pool and the decay math. |
ai-memory-wiki | Atomic markdown writes, the file watcher and git. |
ai-memory-mcp | The MCP transport, the tool router and the admin routes. |
ai-memory-hooks | Hook payload schemas, the sanitizer and the /hook endpoint. |
ai-memory-llm | The provider auth boundary and the LLM and embedder traits. |
ai-memory-consolidate | Ingest, lint, sweep and the auto-improve pipeline. |
ai-memory-web | The read-only /web browser and the /api/v1 JSON routes. |
ai-memory-workstream | Read-only native transcript readers and the launch adapters behind ai-memory run. |
ai-memory-cli | The ai-memory binary and its thin HTTP subcommands. |
Outside crates/
| Directory | What lives there |
|---|---|
companions/ | ai-memory-importer, a standalone package outside the root workspace. Build it with --manifest-path. |
hooks/ | Lifecycle hook bundles, one folder per agent, shell and native. |
evals/ | The benchmark harness. A workspace member that is never shipped. |
docs/ | Architecture, design decisions, install, deploy and usage guides. |
tests/ | End-to-end smoke tests, hook shell tests and fixtures. |
Integration tests live in tests/suite/ inside each crate. Helpers shared between crates go in crates/ai-memory-test-support, which is never shipped.
How pull requests get reviewed
Reviews follow the pull request template, so filling it in honestly is most of the work.
The template is the checklist
It asks what changed, why, a test plan with the gates ticked, commit attribution, release impact and the changelog entry.
Say what kind of release it is
Tick patch, minor or major. A fix filed under “Added” can bump the wrong version, so put the changelog entry under the right heading.
Breaking changes wait for a major
Call them out in the description. They get the breaking-change label and are scheduled, so they do not hold up patch and minor releases.
CI is fast per merge
A merge gates on the fast Linux jobs. The macOS and Windows legs run on a label, nightly or by hand, and always before a release.
Fixes ship first
A bug fix goes out in the next patch release and is not held for feature work. A new harness or provider ships in the next minor.
A harness pull request runs this shorter gate, records the CLI version it was tested against, and includes a manual pass against the real harness.
cargo fmt --check
git diff --check
cargo test --workspace
cargo clippy --workspace --all-targets -- -D warnings
Try it before you change it.
Run it on your own projects for a day. The bug you find is your first issue.